Appearance
Data Engineering SQL Handbook
An interactive Data Engineering SQL curriculum and spaced-repetition practice app — pairing production ANSI SQL cheat sheets, inline-graded quizzes, 15 FAANG interview case studies, and 4 end-to-end capstone pipelines with active recall, memory strength tracking, and zero-backend persistence.
What This Repo Does
Most SQL guides stop at passive reading or isolated puzzle queries. Production data engineering requires defending against silent join fan-outs and three-valued NULL bugs, building idempotent deduplication and SCD Type 2 pipelines, translating idioms cleanly across cloud warehouses, and diagnosing shuffles, spills, and data skew in execution plans.
This repository serves two roles from a single source of Markdown & SQL files:
- Interactive Web Handbook (VitePress): Renders
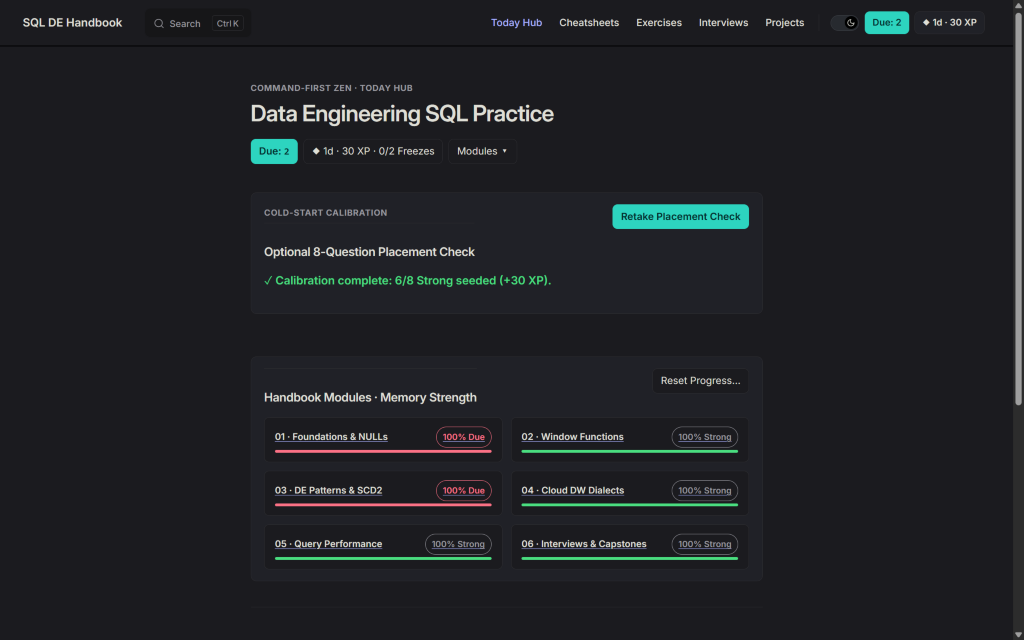
cheatsheets/,exercises/,interviews/, andprojects/alongside client-side learning tools stored under.vitepress/:- Today Hub & 8-Question Placement Check: Calibrates initial module strength in under two minutes without burying you in an artificial backlog.
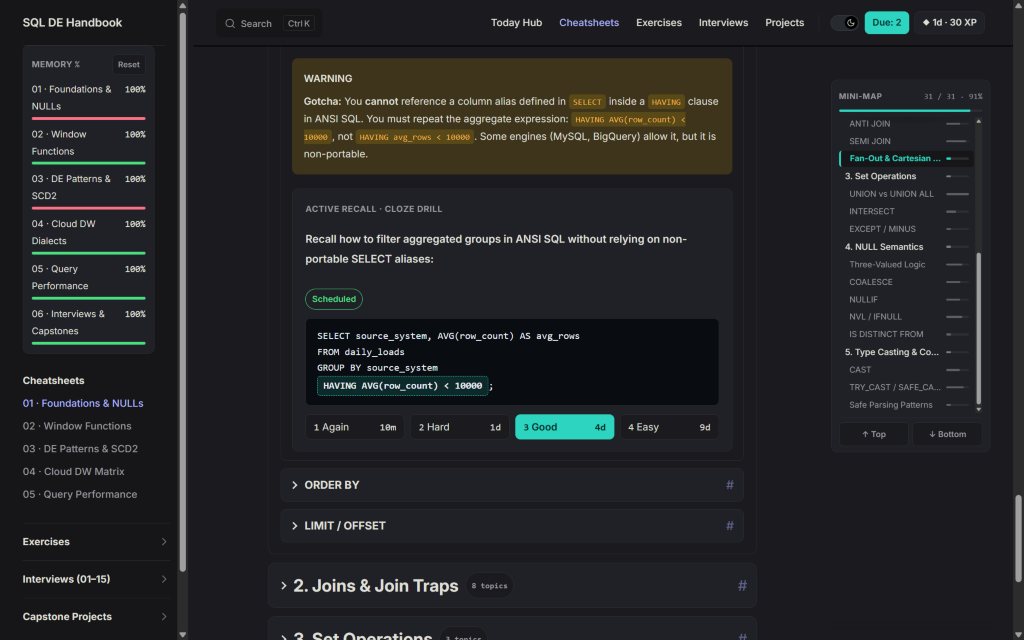
- SM-2 Spaced Repetition & Due Queue: Schedules Recall Cards across review intervals (
Again,Hard,Good,Easy) using keyboard or pointer controls (Space,1–4), tracking XP, daily Consistency Streaks, and up to two earned Streak Freezes. - Cheatsheet Accordions, Cloze Drills & Section Mini-Map: Collapses dense sections into expandable dropdowns, masks key SQL syntax inside interactive Cloze Drills, and provides a sticky right-hand Section Mini-Map for fast jumping.
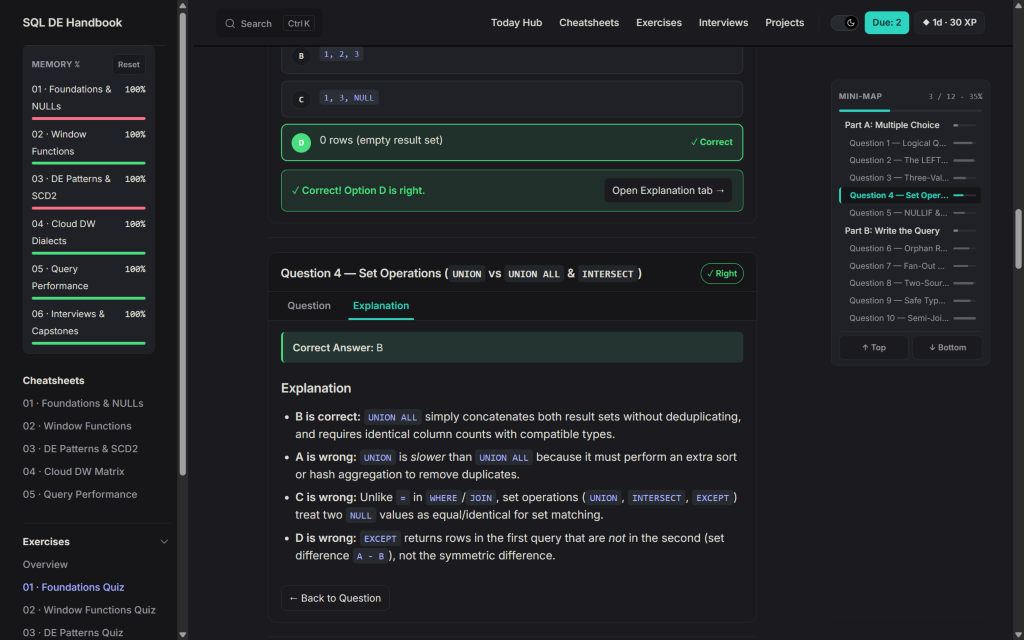
- Single-Page Interactive Quizzes: Click any option to see immediate right/wrong feedback inline, then open the card's Explanation tab for the worked answer and distractor breakdown.
- Non-Executable Cloud Dialect Blocks: Clearly flags Snowflake, BigQuery, Databricks (Spark SQL), and PostgreSQL
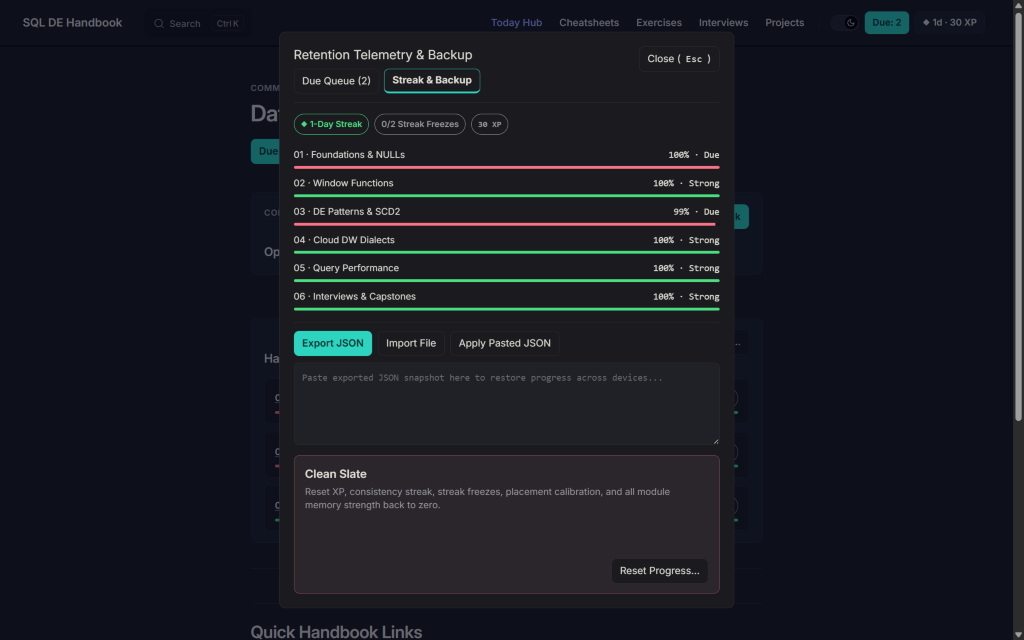
JSONBsnippets with direct links to each vendor's official playground instead of faking local execution. - 100% Client-Side Persistence, JSON Backup & Clean Slate Reset: Saves all progress in
localStoragewith schema-validated JSON export/import and a guarded two-step Clean Slate reset.
- Offline SQL Curriculum (
DuckDB CLI/PostgreSQL): Provides standalone DDL (schema.sql), edge-case mock datasets (seed_data.sql), and heavily commented reference CTE pipelines (solution.sql) for local execution without paid cloud accounts.
Screenshots
1. Today Hub, Placement Calibration & Module Memory Strength
2. Cheatsheets: Collapsible Sections, Cloze Drills & Section Mini-Map
3. Interactive Quizzes with Inline Grading & Explanation Tab
4. Retention Telemetry, Portable JSON Backup & Clean Slate Reset
Quick Start & Setup
Prerequisites
- Node.js
18+(recommended20+LTS) andnpm— for running the VitePress web app and test suite. - (Optional) DuckDB CLI or Docker + PostgreSQL — for executing capstone
schema.sql,seed_data.sql, andsolution.sqlscripts locally.
1. Run the Interactive Handbook Locally
bash
# Clone the repository
git clone <your-repo-url> sql-cheatsheet-DE
cd sql-cheatsheet-DE

# Install dependencies
npm install

# Start the local VitePress dev server with hot reload
npm run docs:dev
Then open the local URL printed in your terminal (typically http://localhost:5173).
Additional npm scripts:
bash
# Build the static production bundle into .vitepress/dist/
npm run docs:build

# Preview the built production bundle locally
npm run docs:preview

# Run the Vitest unit and component test suite
npm test

# Run TypeScript typechecking
npm run typecheck
NOTE
Windows PowerShell users: If script execution policy blocks .ps1 shims, invoke scripts via npm.cmd (for example npm.cmd install, npm.cmd run docs:dev, npm.cmd test, and npm.cmd run typecheck).
2. Practice Capstone SQL Locally (Optional)
You do not need a paid Snowflake, BigQuery, or Databricks account to run the SQL projects in this handbook.
DuckDB CLI (Recommended)
bash
# macOS (Homebrew)
brew install duckdb

# Windows (winget)
winget install DuckDB.cli

# Python package
pip install duckdb
Load any capstone project's schema and seed data directly in DuckDB:
sql
-- From repository root: duckdb practice.duckdb
.mode box
.timer on

.read projects/01-clickstream-sessionization/schema.sql
.read projects/01-clickstream-sessionization/seed_data.sql

.tables
SELECT COUNT(*) AS raw_event_count FROM raw_clicks;
PowerShell / Bash one-liners to populate a local database file:
powershell
# PowerShell
Get-Content projects\04-iot-telemetry-anomaly\schema.sql, projects\04-iot-telemetry-anomaly\seed_data.sql | duckdb iot.duckdb
bash
# Bash / zsh
cat projects/04-iot-telemetry-anomaly/schema.sql projects/04-iot-telemetry-anomaly/seed_data.sql | duckdb iot.duckdb
PostgreSQL via Docker (Optional)
bash
docker run --name de-sql-pg -e POSTGRES_PASSWORD=postgres -p 5432:5432 -d postgres:16
psql "postgresql://postgres:postgres@localhost:5432/postgres" -f projects/02-fintech-scd2-ledger/schema.sql
Curriculum & Quick Navigation
| Area | Resource | Focus & Contents |
|---|---|---|
| Module 1 | Quick Syntax & Foundation Cheat Sheet | Core clauses, joins & fan-out traps, set operations, 3-valued NULL logic, safe casting (TRY_CAST) |
| Module 2 | Advanced Analytical SQL & Window Functions | ROW_NUMBER/RANK/DENSE_RANK/NTILE, LAG/LEAD/FIRST_VALUE/LAST_VALUE, ROWS vs. RANGE frames, recursive CTEs, QUALIFY |
| Module 3 | Production Data Engineering Patterns | Deduplication, CDC & SCD Type 1/2, gaps & islands, 30-min sessionization, JSON/arrays, MERGE upserts, calendar spines |
| Module 4 | Cloud Data Warehouse Nuance Matrix | Side-by-side syntax & behavior matrix for ANSI/DuckDB, Snowflake, BigQuery, and Databricks (Spark SQL) |
| Module 5 | Query Performance, Optimization & Anti-Patterns | EXPLAIN/EXPLAIN ANALYZE, partitioning & clustering, broadcast/hash/sort-merge joins, key salting, SARGability, CTE materialization |
| Exercises | Interactive Practice Quizzes Index | Hands-on module quizzes (quiz.md) with inline option checking and worked Explanation tabs |
| Module 6 | FAANG / Big Tech Interview Masterclass | 15 Medium & Hard SQL interview problems with DDL, sample I/O, brute-force vs. optimal solutions, and follow-ups |
| Projects | Real-Life Capstone SQL Projects | 4 multi-table pipelines: Clickstream Sessionization, FinTech SCD2 Ledger, SaaS MRR Waterfall, IoT Telemetry Anomaly Detection |
Target Audience & Learning Roadmap
| Experience Level | What You Will Gain | Recommended Starting Point |
|---|---|---|
| Beginner / Aspiring DE & Analyst | Master logical query execution order, join semantics, NULL three-valued logic, safe casting, and window functions without data-loss traps. | Module 1 Cheat Sheet & Quiz 01 |
| Mid-Level Data / Analytics Engineer | Implement production pipeline patterns (deduplication, CDC/SCD Type 2, gaps & islands, sessionization, JSON/array handling, idempotent MERGE) across cloud platforms. | Module 3 Cheat Sheet, Module 4 Matrix & Capstone Projects |
| Senior / Staff DE & Interview Candidates | Read EXPLAIN ANALYZE / query profiles, eliminate partition-pruning blockers and join skew via salting, reason about CTE materialization, and solve graph/temporal interview problems. | Module 5 Tuning & Interview Masterclass |
- Step 1 — Nail the Mechanics: Module 1 → Exercises 01
- Step 2 — Think in Windows & Graphs: Module 2 → Exercises 02
- Step 3 — Build Production Pipeline Patterns: Module 3 → Exercises 03
- Step 4 — Bridge Cloud Dialects & Performance: Module 4 & Module 5 → Exercises 04 & 05
- Step 5 — Apply Everything in Capstones: Capstone Projects Hub
- Step 6 — Sharpen Under Interview Pressure: Interview Masterclass
Dialect Focus
- Universal / Dialect-Agnostic ANSI SQL (Primary Baseline): Used across Modules 1–3, Interviews, and Capstone Projects (
schema.sql,seed_data.sql,solution.sql). - Cloud Data Warehouse Nuances: Module 4 and Module 5 compare ANSI/DuckDB, Snowflake, Google BigQuery, and Databricks (Spark SQL), paired with non-executable Dialect Blocks linking directly to each platform's console.
Repository Layout
text
sql-cheatsheet-DE/
├── index.md                               # VitePress Today Hub homepage
├── README.md                              # Project documentation, setup guide & screenshots (this file)
├── GLOSSARY.md                            # Domain vocabulary definitions
├── public/
│   └── favicon.svg                        # Site icon
├── .vitepress/
│   ├── config.mts                         # VitePress site configuration & navigation
│   ├── handbook/                          # Retention store, catalog, quiz enhancer, accordion, mini-map & Vitest suites
│   └── theme/                             # Vue components (TodayHub, ClozeDrill, DueQueueDialog, SectionMiniMap, etc.) & styles
├── docs/
│   ├── adr/                               # Architecture Decision Records
│   ├── agents/                            # Agent/contributor conventions
│   └── screenshots/                       # README showcase screenshots
├── cheatsheets/                           # Modules 1–5 Markdown reference guides
├── exercises/                             # Module 1–5 interactive quizzes (+ build-time explanation sources)
├── interviews/                            # 15 FAANG / Big Tech SQL case studies
└── projects/                              # 4 multi-table capstone SQL pipelines (schema, seed, solution)